

I watched the Super Bowl this year the same way most of us do, half paying attention to the game, genuinely paying attention to the commercials. And somewhere in the second quarter, something started nagging at me.
The AI ads were wall-to-wall. OpenAI ran a spot called “You Can Just Build Things,” built around their Codex product, a tool that lets anyone write software by describing what they want. The message, delivered with Apple-commercial craft and genuine production polish, was simple: the barriers to building software are gone. Anyone can create an app now. Anyone can ship a product. The last few seconds flashed “You Can Just Build Things” on screen, followed by a prompt to consider Codex.1
My gut immediately said: yes, and…
Welcome to the Slop-pocalypse
I have a new term. I don’t love that it needs to be a thing, but it is…
I call it the slop-pocalypse. It is the point at which the sheer volume of AI-generated code flooding into production environments overwhelms our collective ability to validate, maintain, and support it.
We’re not there yet. But the ride is getting bumpy. And I don’t think the turbulence is random.
Some of the tools and services I rely on most, the ones I’ve recommended to clients, the ones I’ve built workflows around, have been going down more often lately. More frequently, and for longer.
I’m not going to hang anyone out to dry by naming names, and I don’t have access to anyone’s incident logs. What I have is a career’s worth of pattern recognition telling me that the frequency of change has outpaced the capacity for validation. My spidey senses are rarely wrong, and they’re not whispering right now.
👇 Turns out, I’m not imagining things.👇
The Outages Are Already Here
The numbers on production reliability in 2025 are not good. Critical and major incidents across popular DevOps platforms like GitHub, Jira, and Azure DevOps increased 69% year over year, with total service degradation time jumping from roughly 4,755 hours in 2024 to over 9,255 hours in 2025.2 That’s not a blip. That’s a trend line.
Global network outages increased 33.38% from January to May 2025 alone. A single AWS outage in October 2025 affected more than 3,500 companies across 60 countries, generated over 6.3 million outage reports from the US alone, and lasted more than 15 hours.3 The cause? A DNS resolution failure was traced to an empty DNS record and incorrect automation updates. One bad automated change. Thousands of downstream casualties.
Only 20% of executives feel fully prepared to respond to outages, even as their organizations endure an average of 86 hours of downtime annually. Fifty-five percent report outages at least weekly.4
Read that last stat again. More than half of organizations experience production outages every week. This is not a technology ecosystem that has its arms around production stability. And we are about to flood it with more AI-generated code than it has ever seen.
This is the slop-pocalypse knocking on the door. 🤜🚪
The Super Bowl Told You So
Those commercials matter beyond the hype, so stay with me.
The overriding message throughout the AI Super Bowl ads was clear: AI means that ordinary people with no training can write computer code and apps.5 Nobody, however, ran a follow-up ad asking: What happens in 18 months?
What happens when the API that the AI-generated app sits on top of releases a breaking change? What happens when the underlying service patches a security vulnerability that happened to be an access vector your app was silently exploiting? What happens when the library your no-code solution depended on gets deprecated, changes its authentication model, or simply stops being maintained?
The person who “just built a thing” with an AI prompt is, in most cases, completely unequipped to answer any of those questions. They don’t know what version of what framework they’re running. They don’t know what dependencies are included. They don’t know what’s held together with solid engineering and what’s held together with digital duct tape. The AI that helped them build it won’t be standing by to bail them out when the scaffolding shifts.
If you want to see what this actually looks like in practice, Michael Paulson — better known as ThePrimeagen, former Netflix engineer and one of the most credible technical voices online — put it plainly in a short called “AI Scuffed Programming.”6 It’s a quick watch, and if you’ve ever watched an AI coding tool confidently produce broken output, it’ll hit home immediately.
I run into this in my own daily work. I use Claude Code every day, and I am constantly — constantly — telling it to reference the latest published documentation for the tools I’m using rather than relying on what it was trained on.
On a regular basis, it suggests what it believes is the correct approach, only for me to realize it’s giving me the right answer for Next.js 14 when I’m running Next.js 16.2. That’s not a knock on the tool. That’s just reality: the model was trained on data up to a certain point, and the ecosystem does not pause for it. Next.js 16.2 shipped in March 2026 with performance improvements, better debugging, over 200 Turbopack fixes, and dedicated AI agent tooling improvements.7
The version gap between “what the AI learned” and “what you’re actually running” is real, it’s growing, and it matters. I know to check. I stay on top of releases.
Most people building apps with AI-generated code have never thought about this for a single second. That’s not an insult, it’s just not their world. The Super Bowl told them it didn’t need to be.
This Isn’t New. The Frequency Is.
Before you close this tab and convince yourself the sky is falling, it isn’t. Not yet, and maybe not at all in the way you’re picturing.
ThePrimeagen’s longer video on this — “You Aren’t Getting Left Behind,” up on ThePrimeagenHighlights — is worth your time precisely because he refuses to catastrophize.8 The developers and leaders who understand systems deeply are not obsolete. They’re about to be more valuable than they’ve been in years. The question is whether your organization will figure that out before the first crisis forces the conversation.
Over my career, I’ve helped dozens of companies that found themselves on the wrong side of their own success. The proof of concept that won the room, that got the funding, that got deployed to real users, was suddenly falling over because it was, in fact, a POC. It was never intended to scale. It was never hardened for production.
Launching with a POC and finding unexpected success isn’t a failure story; it’s a gift. You just have cleanup to do. The problem is when organizations skip the cleanup and call the POC a product. And now we have millions of people skipping the cleanup because they don’t know it exists.
Cory Doctorow captured a related pattern well in his writing on “enshittification”: platforms that prioritize short-term speed over long-term sustainability eventually eat themselves.9 The mechanics here aren’t identical, but the shape of the problem rhymes. Move fast, skip validation, outrun your support capacity, and eventually, the thing you built becomes the thing you’re apologizing for.
The step change isn’t the failure rate of individual code changes. It’s the multiplication effect of velocity. If your team was pushing a handful of changes a week and five percent caused problems, that was manageable. If you’re now pushing hundreds of changes a week because generation velocity has exploded, that same five percent failure rate becomes a crisis you cannot stay ahead of.
The Looming Maintenance Challenge
Here’s something I’ve coached engineering organizations on for years that I think is about to become a full-blown crisis: the ratio of time spent on new feature development versus maintenance: bug fixes, version upgrades, security patches, and dependency management.
A healthy engineering organization runs somewhere around 70% new development, 30% maintenance, and hardening. That’s not an arbitrary number. Each sprint should include 70% of the time for feature development and 30% for product hardening — ensuring the product is both moving forward AND remaining stable under real-world conditions.10 And even that discipline is hard to hold. The reality in many organizations is often very different, with teams spending 40–50% of their time on maintenance and unplanned work.11
That’s in established engineering organizations — teams that have incident response processes, dependency audits, and someone whose job it is to know when a critical security patch drops.
Now think about the wave of AI-generated apps spinning up right now. I will bet significant money that the maintenance allocation for the vast majority of those apps is exactly zero percent. Not because the builders are reckless. Because they don’t know maintenance is a category that requires a budget. They built a thing. The thing works. They shipped it. Done.
Until it isn’t done. Until the security patch drops and none of the three CVEs affect anything the original builder knows how to fix. Until the authentication scheme changes and the app stops working on a Tuesday morning. Poor maintenance allocation creates compounding costs well beyond technical debt — teams end up spending increasing time on firefighting instead of planned work, and unclear allocation decisions erode trust between engineering and business stakeholders.12
That’s in organizations that have engineering stakeholders. Most of the apps being generated right now have an enthusiastic founder, a Codex subscription, and no one on call.
Can LLMs Rescue Us From Themselves?
I genuinely don’t know. And I want to be honest about that, because this space is moving fast enough that anything I say with confidence today might be outdated before this hits your inbox.
There are real arguments on the optimistic side. AI-assisted testing, automated dependency scanning, and AI-driven code review — these are all evolving. Maybe the tools that created the volume can help manage it.
But here’s what I keep coming back to: I’m a technical person who works with these tools every day, and I still have to manually prompt my AI coding assistant to check current documentation rather than rely on its training data. I know what version of Next.js I’m running. I know that middleware.ts was renamed to proxy.ts in version 16, and if I don’t tell the model that, it will give me confident, well-structured, completely wrong guidance. That knowledge doesn’t come from the AI. It comes from years of staying close to the tools.
AI agents currently have a ceiling of between roughly half a million and a few million lines of code they can work with effectively — if your codebase is a monolith that won’t fit in a context window, AI agents simply won’t work well with it.13 The context problem, which is ultimately a requirements and systems-knowledge problem, has been the biggest hurdle in software development for decades. Better tools don’t solve it. People who understand systems deeply enough to describe what they need with precision solve it.
That’s what senior engineers actually do. Not write more code faster. Understand systems well enough to know what shouldn’t be built, what’s already fragile, and what will break quietly in six months if nobody thinks about it. Senior engineers have a massive advantage with AI tools precisely because they know what questions to ask and understand the edge cases — a junior developer accepts the first output; a senior engineer knows what’s missing.14
The slop-pocalypse, IF it fully arrives, won’t be solved by a smarter model. It’ll be solved by people who never stopped owning the work.
At least that is my bet, but I REALLY don’t know how this is going to shake out. No one does. Don’t forget that.
What This Means For You Right Now
I’m not writing this to tell you the sky is falling. I’m writing it because inflection points reward the people who see them clearly.
Think about everything we’ve covered in this article. The 70/30 split between building and maintaining. Dependency audits. Version tracking. Incident response processes. Knowing what frameworks you’re running and what breaking changes are coming. Having someone on the team whose job it is to care about that stuff.
Those aren’t things a good engineering team decides to do on a Monday morning. Those are things they fought to put in place.
Fought with leadership who wanted every sprint to be new features.
Fought with timelines that left no room for hardening.
Fought through quarters of “we’ll clean it up later” before someone finally made the case that later was already here.
The best engineering organizations I’ve worked with spent years earning those disciplines — negotiating for the capacity, proving the value, and slowly building the culture that treats maintenance as a first-class citizen rather than a sign of failure.
That infrastructure: the processes, the guardrails, the institutional knowledge, exists because someone paid for it in time, political capital, and hard lessons.
Now zoom out. Your organization just handed a code generator to everyone with a business idea and an internet connection. The Super Bowl told them they could build anything. Codex, Cursor, Claude Code — take your pick, they’re all remarkable tools. And the apps being produced are real. They work. They’re going into “production”. Some of them are becoming mission-critical faster than anyone planned for, because that’s what happens when something works.
But how many of those apps have a maintenance budget? How many have a dependency audit scheduled? How many have anyone on point for the next CVE that drops in a framework they’re running, a framework they may not even know they’re running? How many have an incident response plan that goes beyond “post in Slack and hope”?
If you’re running an engineering organization, this is the conversation you need to be having right now — not when the first crisis hits. The guardrails your team spent years putting in place exist precisely because software without them eventually breaks in ways that are expensive, embarrassing, and entirely predictable in hindsight. Vibe coding your way to production doesn’t repeal that law. It just means nobody read it before signing.
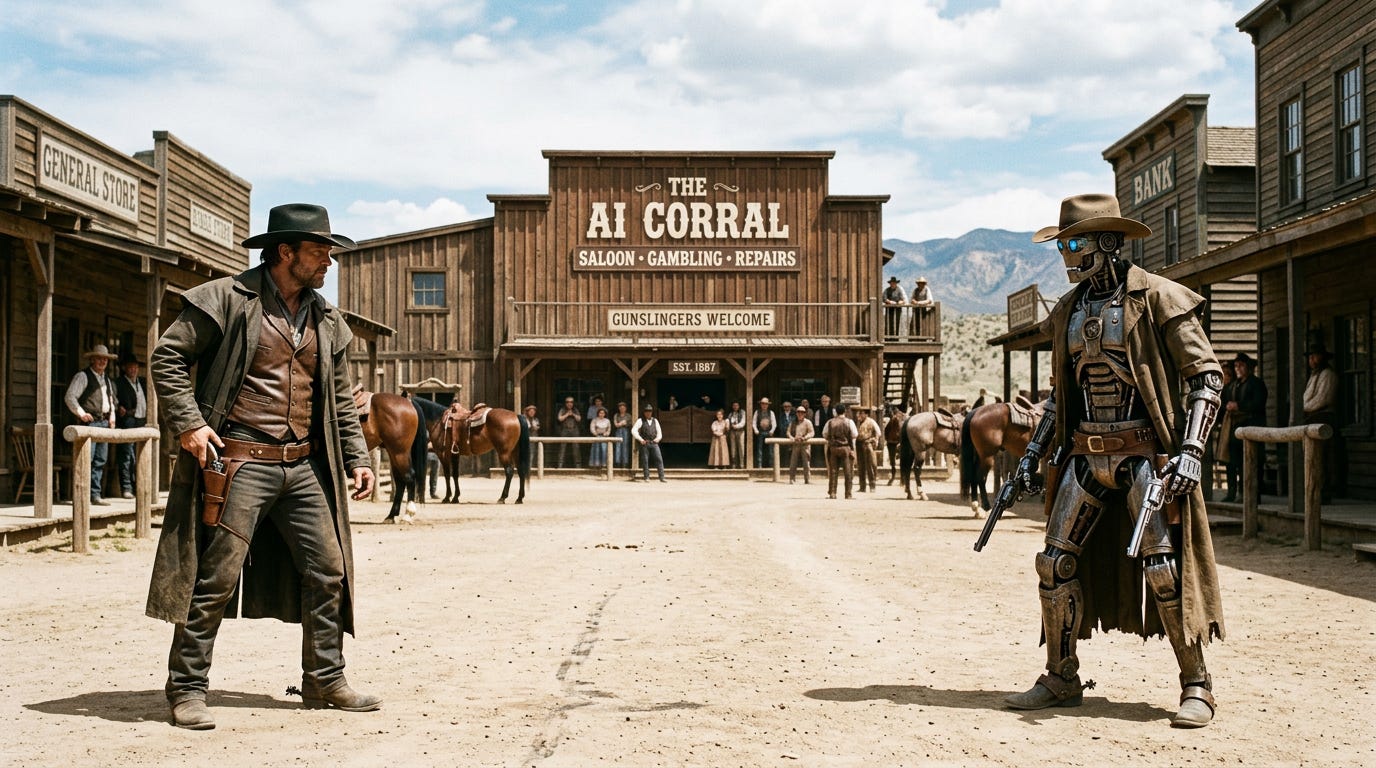
The showdown at the AI corral is happening whether you’re ready or not. Everybody has a code generator now. The question is who’s still around to fix it when it breaks.
Stay courageous,
Josh Anderson
The Leadership Lighthouse
GitProtect / The Hacker News — DevOps & SaaS Downtime report, January 2026.
DemandSage — Internet Outage Statistics 2025–2026, December 2025.
Cockroach Labs — 2025 Top Outages report.
CNN Business — Super Bowl ads want you to stop worrying and learn to love AI, February 2026.
ThePrimeagen — “AI Scuffed Programming” (YouTube Short).
Next.js — Next.js 16.2 release notes, March 2026.
ThePrimeagenHighlights — “You Aren’t Getting Left Behind”.
Cory Doctorow — The ‘Enshittification’ of TikTok, Pluralistic, January 2023.
Solid Digital — The 70/30 Rule for digital product development.
Swarmia — Engineering metrics leaders should track in 2026, January 2026.
Uplevel — KTLO in Software Development, August 2025.
Pragmatic Engineer / Steve Yegge — From IDEs to AI Agents, March 2026.
Frontend Masters — What Senior Engineers Need to Know About AI Coding Tools.
Not related (but maybe relevant) and needed to call out ..
Long live the Don Quixote managers! This metacast was huge, we need more managers in the "minority" and maybe you can rally them here. ♥️
Thank you. This summed up my general thoughts about AI and what happens when there isn’t an expert to figure what went wrong and where it fell apart.